Kimi K3.1 Pro: Benchmarks, Pricing, Open Weights & What Changed from K3
October 25, 2026 · kimi k3.1 pro · kimi k3.1 · kimi 3.1 · kimi k3.1 pro pricing · kimi k3.1 pro benchmarks · kimi k3.1 open weights · kimi k3.1 vs k3 · kimi k3.1 pro highspeed
Kimi K3.1 Pro is Moonshot AI’s new flagship, released on October 23, 2026, and it is the biggest jump the K3 family has had. It keeps K3’s 3T-class base and 1M-token context, but adds far more post-training. The result scores 55 on Artificial Analysis’s Intelligence Index (up 11 points from K3, #4 of 215 models) and costs a third less: $2 input / $10 output per million tokens, against $3/$15 for K3. It is live now on kimi.com, Kimi Work, Kimi Code and the API (kimi-k3.1-pro). Moonshot says the open weights ship by November 4, 2026.
That makes K3.1 Pro the first (soon-to-be) open-weight model to land within three index points of the best closed model, Claude Opus 5.5 (58), at half its token price. It is not a clean sweep. It trails badly on scientific terminal work and offensive security, and most of the benchmark numbers are still Moonshot’s own.
If you searched for “Kimi K3.1” or “Kimi 3.1”: there is no plain K3.1 yet. Moonshot calls K3.1 Pro “the first model in the K3.1 series”, and the only two models released are K3.1 Pro and K3.1 Pro Highspeed.
This guide covers what changed from K3, the full benchmark table (including where it loses), pricing and plan access, the open-weights and cyber story, and who should switch. Everything below was checked on October 25, 2026 against Moonshot’s launch post, the API quickstart, the Kimi Code model page and Artificial Analysis.
Kimi K3.1 Pro at a glance
| Kimi K3.1 Pro | Kimi K3 | |
|---|---|---|
| Released | October 23, 2026 | July 16, 2026 |
| Base | Post-trained K3, much larger post-training compute | Original release |
| Parameters | 3T-class MoE (reported 2.8T total, ~104B active) | 2.8T total, ~104B active |
| Context window | 1,048,576 tokens | 1,048,576 tokens |
| Max output | 131,072 default, up to 1,048,576 | 131,072 default |
| Input | Text, image, video | Text, image, video |
| Thinking | Always on; low / high / max | low / high / max |
| API price (in / out) | $2 / $10 | $3 / $15 |
| Cache-hit input | $0.20 | $0.30 |
| AA Intelligence Index v4.3.2 | 55 (#4 of 215) | 44 |
| Output speed, Moonshot API | ~73.5 tok/s | ~35 tok/s |
| Open weights | Promised by Nov 4, 2026 | Released July 27, 2026 |
| License | Not announced yet | Custom Kimi K3 License |
Two details deserve attention. First, this is the same model family, not a new architecture. Moonshot describes it only as “a post-trained version of Kimi K3”, and press reports give the same 2.8T total and 104B active figures. Moonshot’s own pages say “3T-class” rather than a precise number. Second, the speed doubled on Moonshot’s standard endpoint. K3 was known for being slow at around 35 tokens per second, and Artificial Analysis now measures K3.1 Pro at 73.5 tok/s with a 2.97-second time to first token. That is still below the median of models it tracks (82 tok/s), but it changes how usable the standard tier feels for interactive work.
What actually changed from K3
Moonshot’s launch post leads with four areas. Here they are with the numbers it published.
1. Agentic coding, a huge jump on Terminal-Bench
Terminal-Bench 4.0 is where the difference is most visible. Kimi K3 scored about 13% on Artificial Analysis’s run. K3.1 Pro scores 65.7% in Moonshot’s run (Claude Code harness) and 67.2% on Artificial Analysis’s independent run with a different harness. That moves Kimi from far behind Claude and GPT to level with them on the benchmark coding agents care about most.
On Moonshot’s internal Kimi Code Bench 3.0 (long-horizon), K3.1 Pro scores 61.2 against K3’s 55.95. GPT-6 Astra still leads that one at 66.5.
2. Far fewer made-up facts
This may be the change you notice first in daily use. On Moonshot’s internal Kimi Hallu Bench Hard (with tools), the claim-level hallucination rate fell from 23.4% for K3 to 8.3%. Without tools it scored 5.4%.
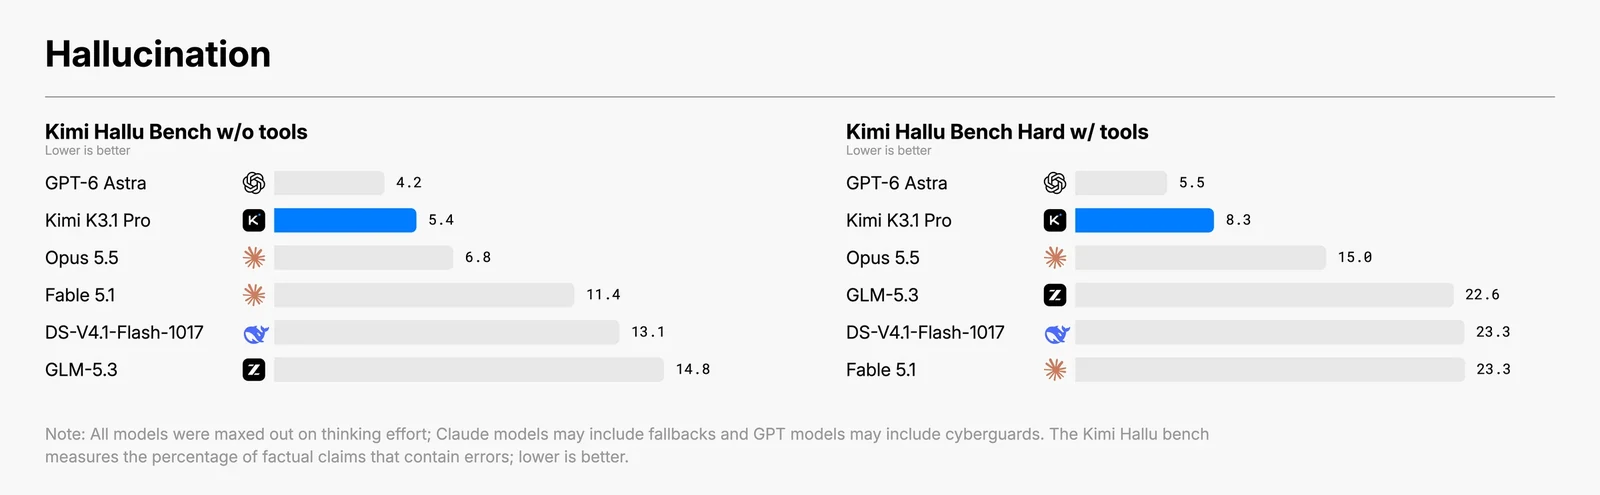
Source: Moonshot AI, Kimi K3.1 Pro launch post.
For context on the same test:
| Model | Hallu Bench, no tools | Hallu Bench Hard, with tools |
|---|---|---|
| GPT-6 Astra | 4.2% | 5.5% |
| Kimi K3.1 Pro | 5.4% | 8.3% |
| Claude Opus 5.5 | 6.8% | 15.0% |
| Claude Fable 5.1 | 11.4% | 23.3% |
| DeepSeek V4.1 Flash (1017) | 13.1% | 23.3% |
| GLM-5.3 | 14.8% | 22.6% |
| Kimi K3 | n/a | 23.4% |
Lower is better. Moonshot says these are stress-test rates on deliberately hard prompts and “do not represent overall error rates in daily use”. It is also an internal benchmark, and the API quickstart quotes a different figure (6.85%) than the launch post (8.3%), so treat the exact number loosely. The direction is not in doubt.
3. Finance and office work
Moonshot pushed hard on spreadsheet and finance tasks:
- OfficeQA Pro v2: 64.4, the top score among the models Moonshot tested (Opus 5.5: 62.2, GPT-6 Astra: 54.4).
- Frontier Finance: 58.6, second behind Claude Fable 5.1 (60.8).
- Internal Financial Modeling: 57.6 vs K3’s 50.4 (+7.2).
- Internal Financial Research: 70.4 vs K3’s 58.8 (+11.6).
- Internal Business Operation: 37 vs K3’s 8.9, about 4.2x.
- GDPval-AA: 312 Elo points above K3 on Artificial Analysis’s run.
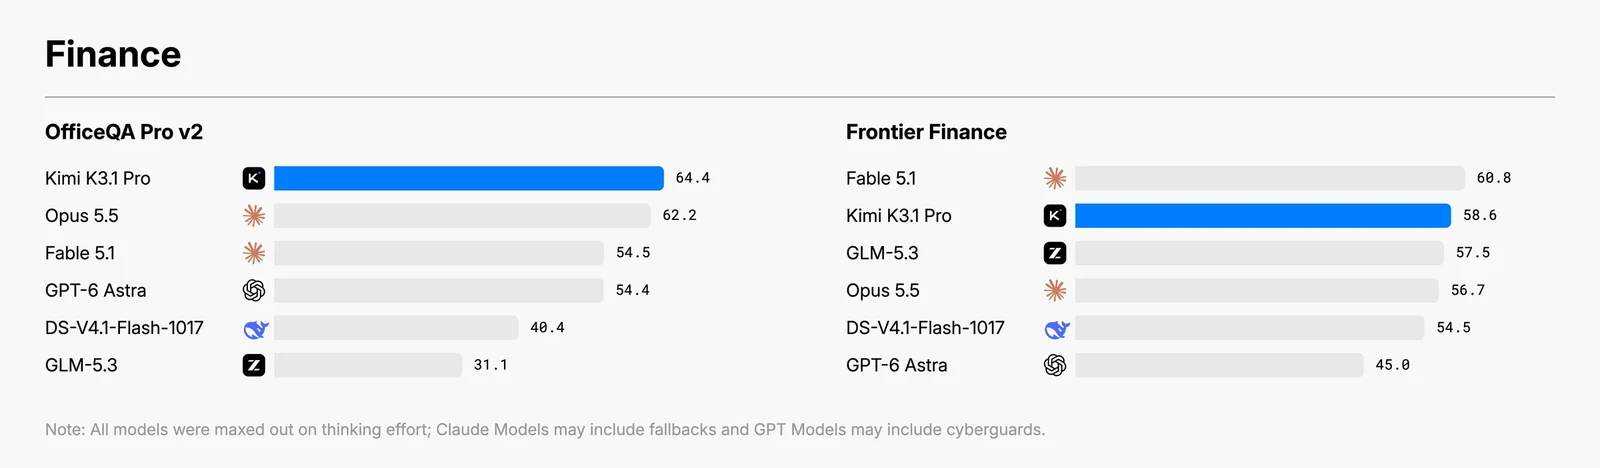
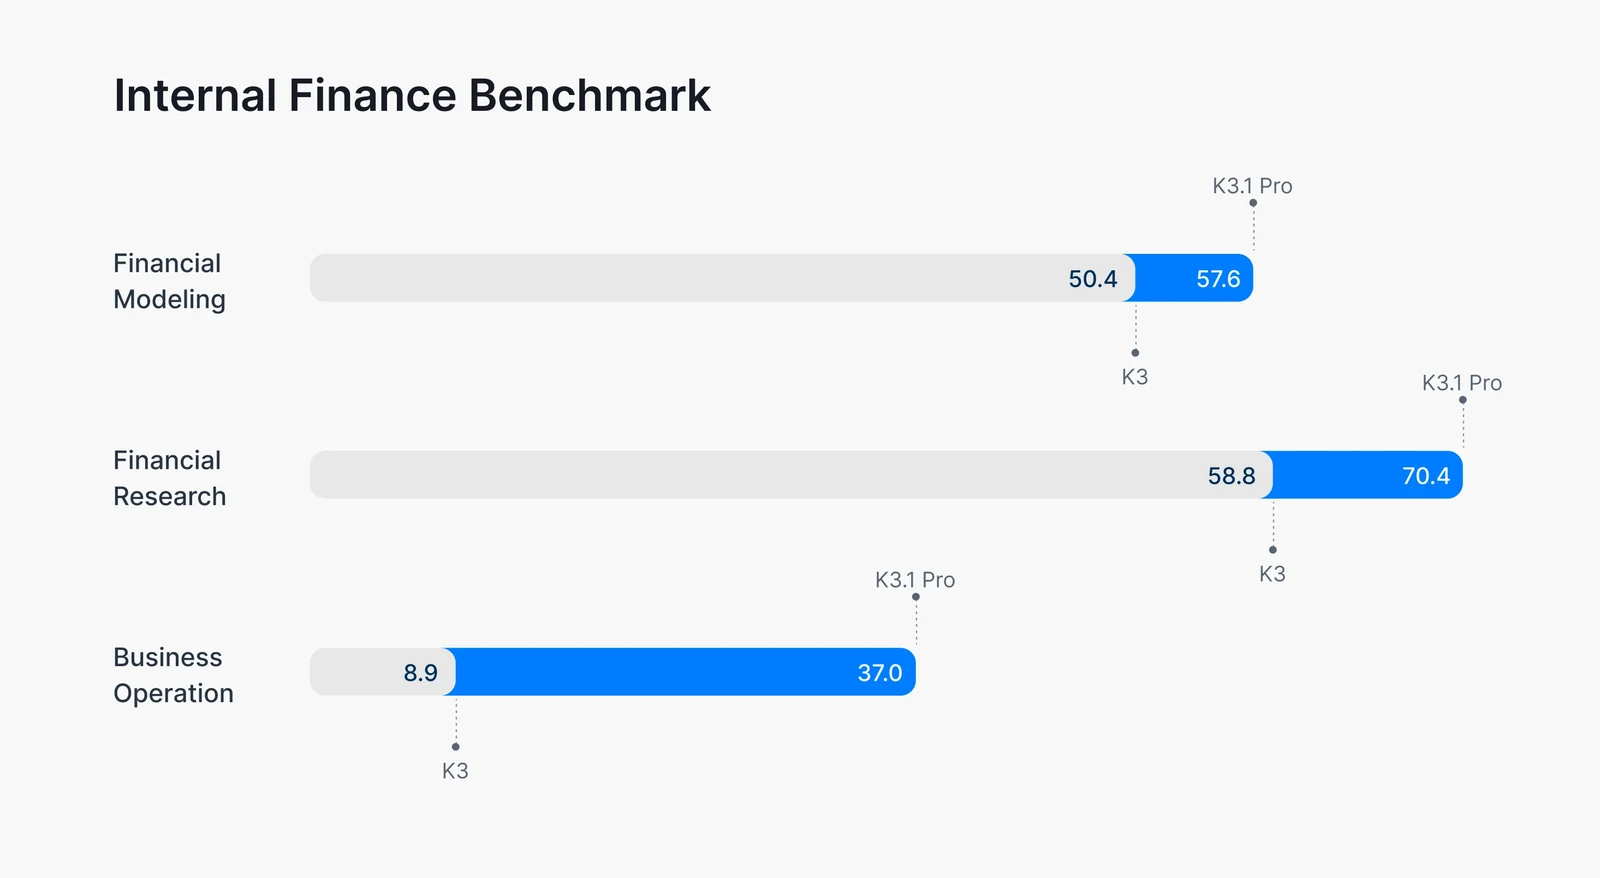
Source: Moonshot AI, Kimi K3.1 Pro launch post. Note that Claude Fable 5.1 still leads Frontier Finance.
4. 3D, CAD and game engines
The launch post spends a lot of space on 3D. K3.1 Pro scores 92.7 on BenchCAD with tools (Opus 5.5: 96.2) and 72.8 without (Opus 5.5: 73.0).
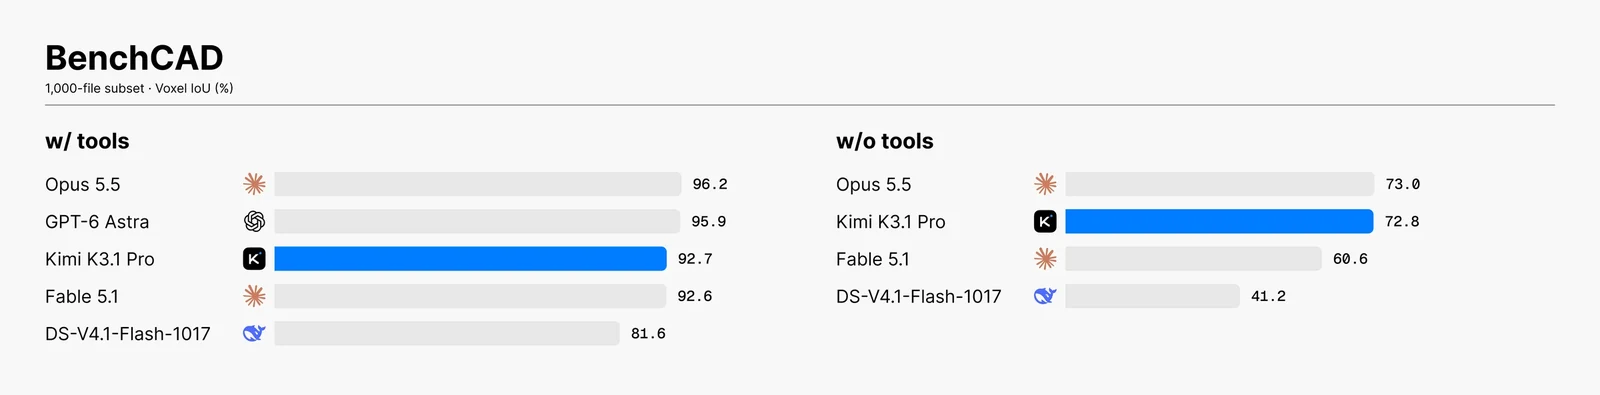
Source: Moonshot AI, Kimi K3.1 Pro launch post. Moonshot says it writes and runs Blender and CAD scripts directly and works with Unity, Unreal Engine and Godot. Alongside the model it launched 3D Make on kimi.com and the Kimi app, where you can preview and edit generated 3D models, download them for 3D printing, or export videos and Live Photos.
Kimi K3.1 Pro benchmarks: the full table
These are Moonshot’s own numbers at maximum reasoning effort. Moonshot notes that Claude results may include fallbacks and GPT results may include cyberguards, and most coding benchmarks ran in the Claude Code harness. Here are Moonshot’s official launch charts:
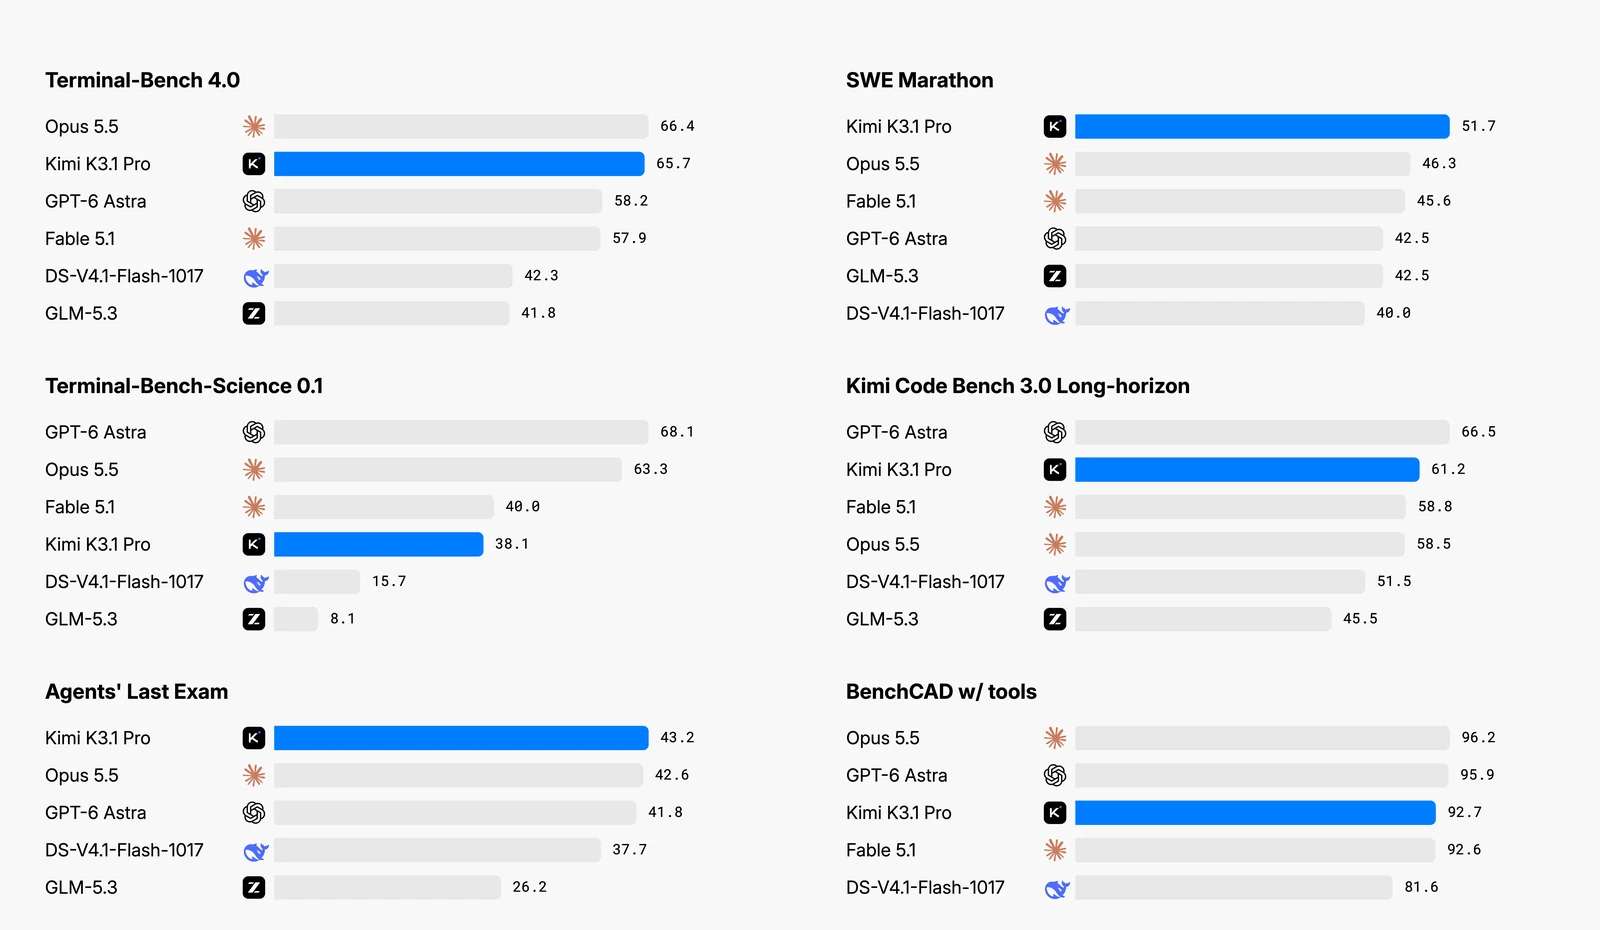
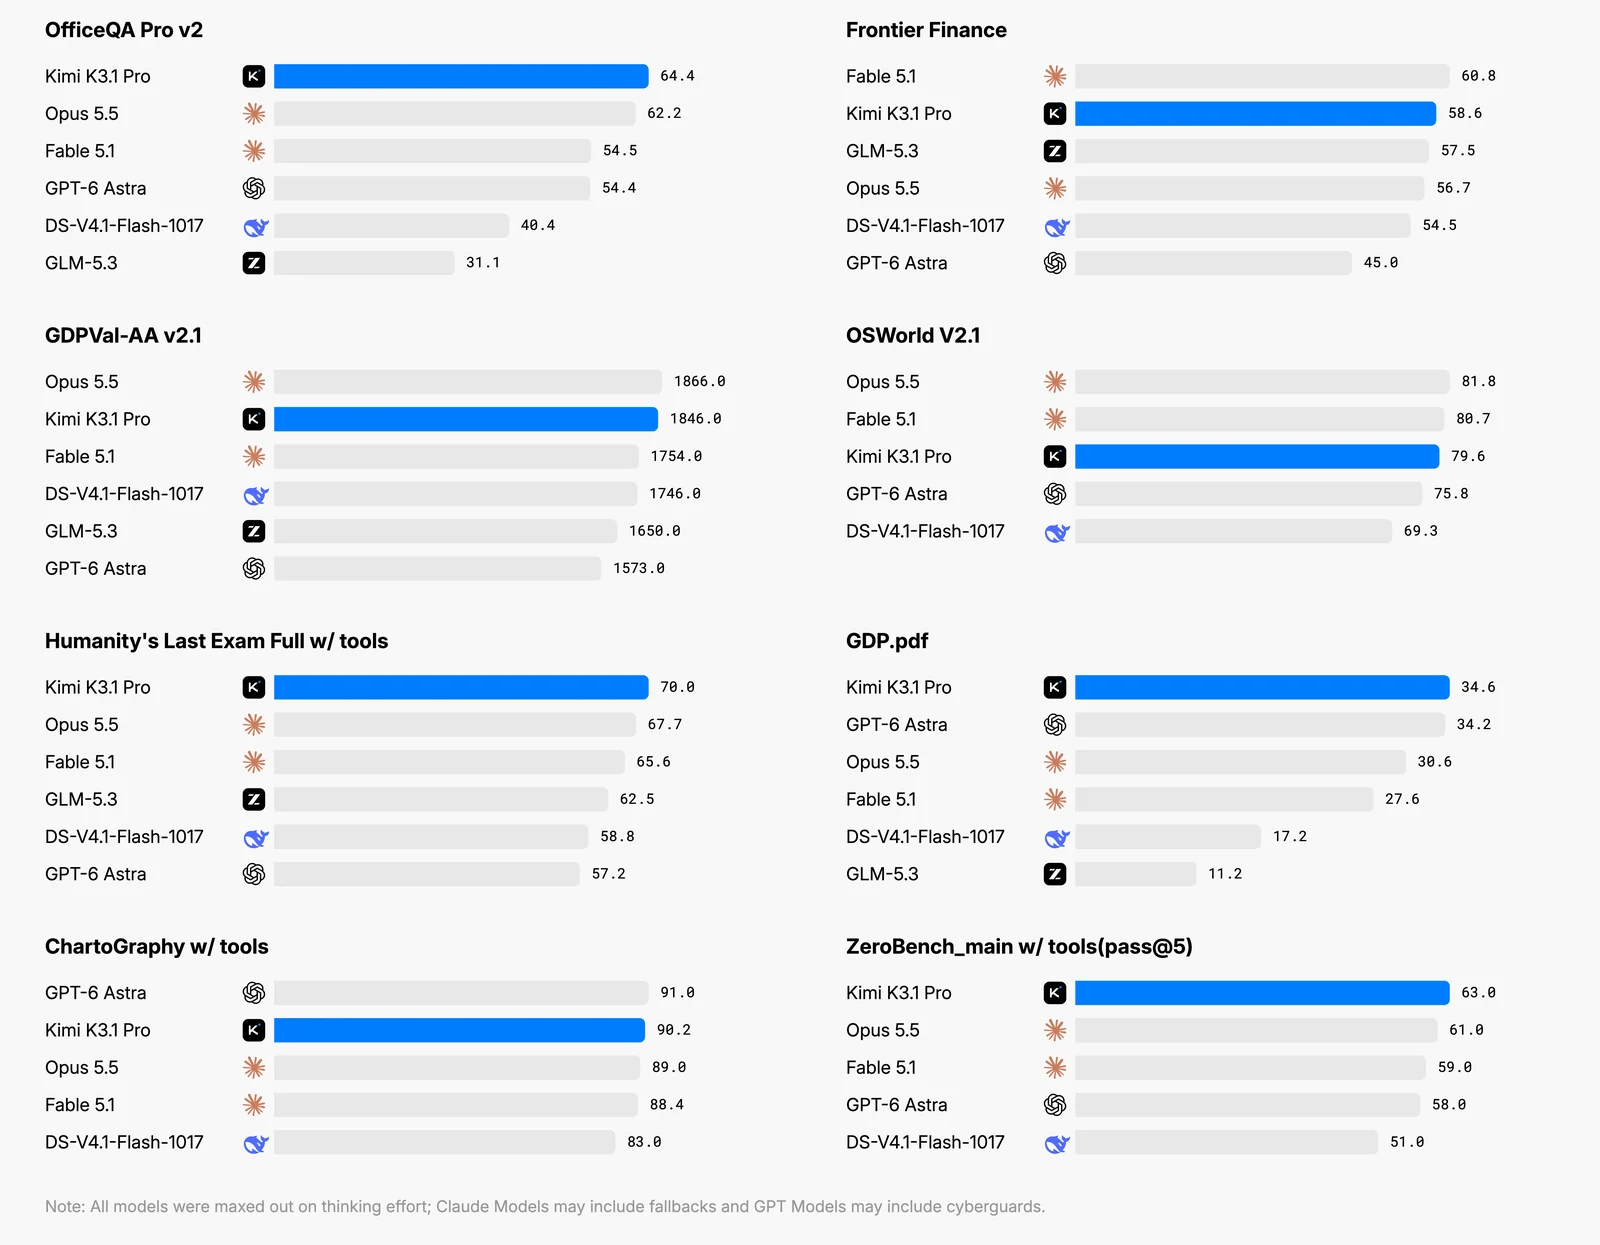
Source: Moonshot AI, Introducing Kimi K3.1 Pro, October 23, 2026.
The same numbers as a table, plus five benchmarks Moonshot reported outside this chart grid:
| Benchmark | K3.1 Pro | Claude Opus 5.5 | GPT-6 Astra | Claude Fable 5.1 | DeepSeek V4.1 Flash | GLM-5.3 |
|---|---|---|---|---|---|---|
| Terminal-Bench 4.0 | 65.7 | 66.4 | 58.2 | 57.9 | 42.3 | 41.8 |
| SWE-Marathon v1.1 | 51.7 | 46.3 | 42.5 | 45.6 | 40.0 | 42.5 |
| Kimi Code Bench 3.0 (long-horizon) | 61.2 | 58.5 | 66.5 | 58.8 | 51.5 | 45.5 |
| DeepSWE v1.1* | 75.5 | 74.2 | 74.1 | 67.4 | 77.0 | 66.9 |
| Terminal-Bench Science 0.1 | 38.1 | 63.3 | 68.1 | 40.0 | 15.7 | 8.1 |
| Agents’ Last Exam | 43.2 | 42.6 | 41.8 | n/a | 37.7 | 26.2 |
| Humanity’s Last Exam Full (tools) | 70.0 | 67.7 | 57.2 | 65.6 | 58.8 | 62.5 |
| BrowseComp* | 92.1 | 90.8 | 91.5 | n/a | n/a | n/a |
| OfficeQA Pro v2 | 64.4 | 62.2 | 54.4 | 54.5 | 40.4 | 31.1 |
| Frontier Finance | 58.6 | 56.7 | 45.0 | 60.8 | 54.5 | 57.5 |
| GDP.pdf | 34.6 | 30.6 | 34.2 | 27.6 | 17.2 | 11.2 |
| Automation Bench-AA* | 73.3 | 69.5 | 68.5 | 59.4 | 66.6 | 62.2 |
| GDPval-AA v2.1 (Elo) | 1,846 | 1,866 | 1,573 | 1,754 | 1,746 | 1,650 |
| GPQA Diamond* | 94.2 | 93.9 | 96.1 | 93.7 | 92.2 | 91.7 |
| OSWorld V2.1 | 79.6 | 81.8 | 75.8 | 80.7 | 69.3 | n/a |
| BenchCAD (tools) | 92.7 | 96.2 | 95.9 | 92.6 | 81.6 | n/a |
| ChartoGraphy (tools) | 90.2 | 89.0 | 91.0 | 88.4 | 83.0 | n/a |
| ZeroBench main (tools, pass@5) | 63.0 | 61.0 | 58.0 | 59.0 | 51.0 | n/a |
| ExploitBench* | 74.7 | 91.0 | 100 | 83.0 | n/a | 54.4 |
*Rows marked with an asterisk are not in the chart grid above; we took them from Moonshot’s figures as compiled by The Decoder. “n/a” means Moonshot did not chart that model.
Out of 19 benchmarks, K3.1 Pro is first on 8 and within one point of first on two more (Terminal-Bench 4.0 and ChartoGraphy).
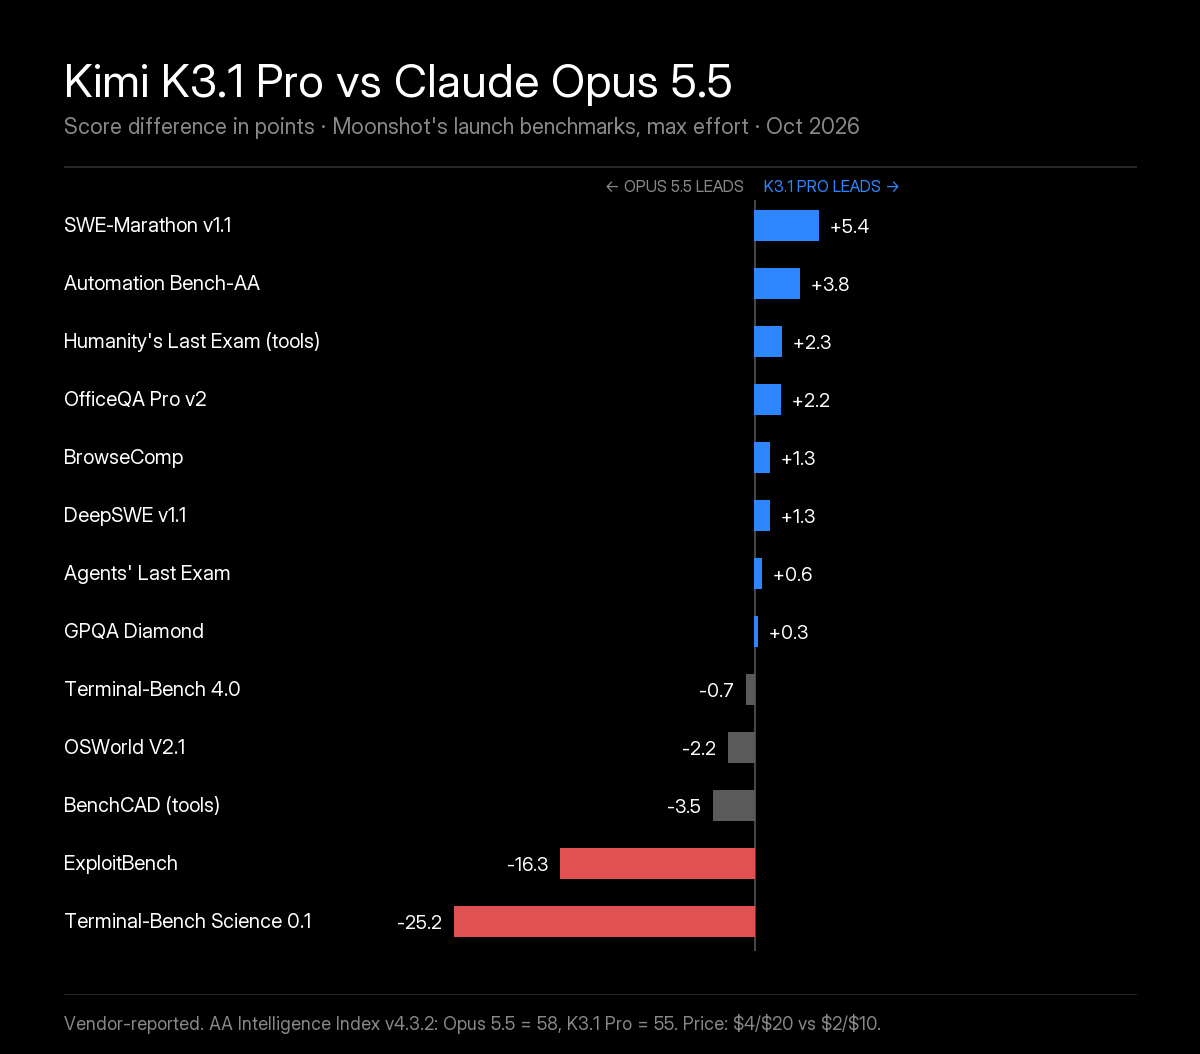
The pattern is clear from the chart. On long-horizon software engineering, research with tools, browsing and office tasks, K3.1 Pro edges out Opus 5.5 by a few points. On computer use and CAD it is a few points behind. On two benchmarks it is far behind: ExploitBench (-16.3), which Moonshot cut on purpose (more below), and Terminal-Bench Science (-25.2), where it scores 38.1 against Opus 5.5’s 63.3 and GPT-6 Astra’s 68.1. If your agents run scientific computing in a terminal, this is not your model.
What the independent numbers say
Artificial Analysis is the main independent source so far:
| AA metric | Kimi K3.1 Pro |
|---|---|
| Intelligence Index v4.3.2 | 55, #4 of 215 |
| Ahead of it | Claude Opus 5.5 (58), Claude Sonnet 5.5 (56), Muse Wonder Full (56) |
| Just behind | Claude Fable 5.1, GPT-6 Astra, Gemini 4 Argon (53 each, per Simon Willison) |
| Terminal-Bench 4.0 (AA harness) | 67.2% |
| Humanity’s Last Exam | 52.5% |
| AA Cyber Index | 64%, top open model |
| Output speed / TTFT | 73.5 tok/s / 2.97s |
| Output tokens to run the index | 150M (median: 87M) |
| Cost per index task | ~$2 |
Two caveats. AA labels it proprietary until the weights actually ship, and if they do, the gap between the best open and best closed model on its index drops from 12 points to 3. And K3.1 Pro is verbose: 150M output tokens to run the index puts it at the high end. The Decoder reports it writes about 14% more output tokens per task than K3, which is why AA’s cost per task stays almost flat even though the per-token price fell by a third.
Independent coverage is still thin beyond AA. One reviewer reported a mismatch between Kimi’s billed balance and the cost they calculated from logged tokens, which Moonshot has not explained. It is worth checking your own billing during the first week.
Kimi K3.1 Pro pricing
Moonshot’s API prices, per million tokens:
| Line item | K3 | K3.1 Pro | K3.1 Pro Highspeed |
|---|---|---|---|
| Cache-hit input | $0.30 | $0.20 | $0.20 |
| Input (cache miss) | $3.00 | $2.00 | $4.00 |
| Output | $15.00 | $10.00 | $20.00 |
| Cache write, 5-min TTL | $3.00 | $2.00* | n/a |
| Cache write, 1-hour TTL | $6.00 | $4.00* | n/a |
| Context tiering | None | None | None |
*Cache-write rates for K3.1 Pro follow K3’s structure at the new input price, as reported by kimi-k2.org. Moonshot’s live price table renders in the browser only; confirm there before you build a budget on it.
Pricing is flat across the whole 1M window, so a 900K-token prompt costs the same per token as a 2K one. Highspeed doubles input and output prices for what Moonshot says is 2-3x the speed, with the cache-hit rate unchanged. The API unlocks after a $1 minimum top-up, and your cumulative top-up sets your rate limits. Zero Data Retention is available to API customers.
How it compares with other frontier models
| Model | Input | Cached input | Output | AA Index |
|---|---|---|---|---|
| Kimi K3.1 Pro | $2 | $0.20 | $10 | 55 |
| Kimi K3 | $3 | $0.30 | $15 | 44 |
| Claude Opus 5.5 | $4 | $0.20 | $20 | 58 |
| GPT-6 Astra | $10 | $1.00 | $50 | 53 |
| Claude Fable 5.1 | $10 | n/a | $50 | 53 |
K3.1 Pro is half Opus 5.5’s input and output price and a fifth of GPT-6 Astra’s. Its cache-read price now matches Opus 5.5’s, which removes one of the arguments we made against K3 in our K3 vs Opus 5.5 comparison.
A quick cost example
A long agentic coding session: 6M input tokens, 90% cache hits (Moonshot’s typical rate for coding), 600K fresh tokens written to a 5-minute cache, and 250K output tokens.
| Kimi K3 | Kimi K3.1 Pro | |
|---|---|---|
| Cache hits (5.4M) | $1.62 | $1.08 |
| Cache writes (0.6M) | $1.80 | $1.20 |
| Output (0.25M) | $3.75 | $2.50 |
| Total | $7.17 | $4.78 |
If K3.1 Pro writes 14% more output for the same job, its output line rises to about $2.85 and the total to about $5.13, still 28% cheaper than K3. The saving is real, just smaller than the headline 33%.
Where you can use Kimi K3.1 Pro
| Channel | How | Who gets it |
|---|---|---|
| kimi.com and Kimi apps | Pick K3.1 Pro in Kimi Agents (iOS, Android, HarmonyOS, web) | Paid plans |
| Kimi Work | Desktop app v3.1.0+ for Windows and Apple silicon Macs | Paid plans |
| Kimi Code | /model and pick k3.1-pro or k3.1-pro-highspeed | Plus / Moderato and above |
| Kimi API | kimi-k3.1-pro, kimi-k3.1-pro-highspeed at https://api.moonshot.ai/v1 | Anyone after a $1 top-up |
| OpenRouter | moonshotai/kimi-k3.1-pro | Routes only to Moonshot’s own two endpoints so far |
| Kimi Business | Admin must turn it on | Off by default at launch |
Kimi Code plan rules
From Moonshot’s Kimi Code model page:
- K3.1 Pro: Plus and above (Moderato and above on legacy plans).
- Full 1M context: Pro and above (Allegretto and above on legacy plans).
- K3.1 Pro Highspeed: Pro and above (Allegretto and above), and it uses about 2x the quota of regular K3.1 Pro.
- Default reasoning effort in Kimi Code is
high, while the raw API defaults tomax.
For reference, the relaunched plans cost ¥49 (Go), ¥99 (Plus), ¥199 (Pro) and ¥699 (Max) a month billed monthly. Go has no Kimi Code quota, so ¥99 is the entry price for K3.1 Pro in Kimi Code. Our Kimi Code setup guide covers the CLI, VS Code and third-party tools.
No hyperscalers yet
Unlike K3, which reached Amazon Bedrock on September 18 and 14+ third-party hosts, K3.1 Pro is Moonshot-only for now. Artificial Analysis lists two providers, and both are Moonshot’s standard and Highspeed endpoints. That will almost certainly change once the weights are public, as it did with K3. Until then, if you need Bedrock, a US-hosted provider or fine-tuning, you are still on K3. See every Kimi K3 API provider for that list.
Developer gotchas before you switch
The API quickstart has several rules that will break existing K3 code if you just swap the model ID:
- Thinking cannot be turned off. Requests that disable it get an HTTP 400. Set
reasoning_efforttolow,highormaxinstead. If you were running K3 with thinking off for speed, budget for reasoning tokens. - Sampling parameters are locked.
temperature(1.0),top_p(0.95),n(1),presence_penaltyandfrequency_penalty(0) are fixed. Remove them from your requests. - No public image URLs. Images must be base64 or an uploaded
ms://<file-id>. Video goes through the files API withpurpose="video". - Do not switch models mid-session. Moonshot warns that moving a K3, K2.8 Preview or K2.7 Code session over to K3.1 Pro lowers quality and cache hits. Start a fresh session.
- Typos fail silently in Kimi Code. A mistyped model ID falls back to K2.8 Preview without thinking, with no error. Check which model actually answered.
- Official web search is not production-ready. The quickstart says it is “being updated and is not recommended for production workflows in the near term.”
- Watch output length. Default
max_completion_tokensis 131,072 and it can go to the full 1M, and the model is verbose. Set a cap.
A minimal call looks like this:
from openai import OpenAI

client = OpenAI(api_key="YOUR_MOONSHOT_API_KEY", base_url="https://api.moonshot.ai/v1")

resp = client.chat.completions.create(
    model="kimi-k3.1-pro",
    messages=[{"role": "user", "content": "Find the race condition in this file"}],
    reasoning_effort="high",      # low / high / max (default max)
    max_completion_tokens=32000,  # cap it; the model is verbose
)
print(resp.choices[0].message.content)
Structured output (json_schema with strict: true), partial mode, custom tools with tool_choice: "required" and automatic context caching all work as they did on K3.
Open weights, license and the cyber cut
Weights: Moonshot’s exact words are “Full model weights will be released by Nov 4, 2026.” As of October 25 there is no K3.1 repository on Moonshot’s Hugging Face page. K3 kept a similar promise: announced July 16, weights out July 27.
License: not announced. K3 shipped under the custom Kimi K3 License, which is not MIT and includes a separate-agreement clause for Model-as-a-Service businesses above $20M revenue. Assume something similar until Moonshot publishes the terms, and do not plan a commercial deployment around K3.1 weights before then.
Hardware: if the architecture really is unchanged, the numbers in our Kimi K3 VRAM guide carry over: about 1.56TB of weights, 1.7-1.84TB to serve, and 8xB300 or 16xH200 as practical minimums. We will update this once the actual files are up.
The cyber cut. This is the most unusual part of the launch. Moonshot says it removed cyberattack-related data from mid-training and RL environments for the open-weight release, because downloaded weights can’t be recalled. On its internal xdev-bench-hard (exploiting real software flaws, pass@3):
| Model | xdev-bench-hard |
|---|---|
| GPT-5.6 Sol (third-party eval) | 100 |
| Kimi checkpoint without the cyber cut | 90.5 |
| DeepSeek V4.1 Flash | 85.7 |
| Kimi K3.1 Pro (released) | 81.0 |
| GLM-5.3 | 57.1 |
| Kimi K3 | 33.3 |
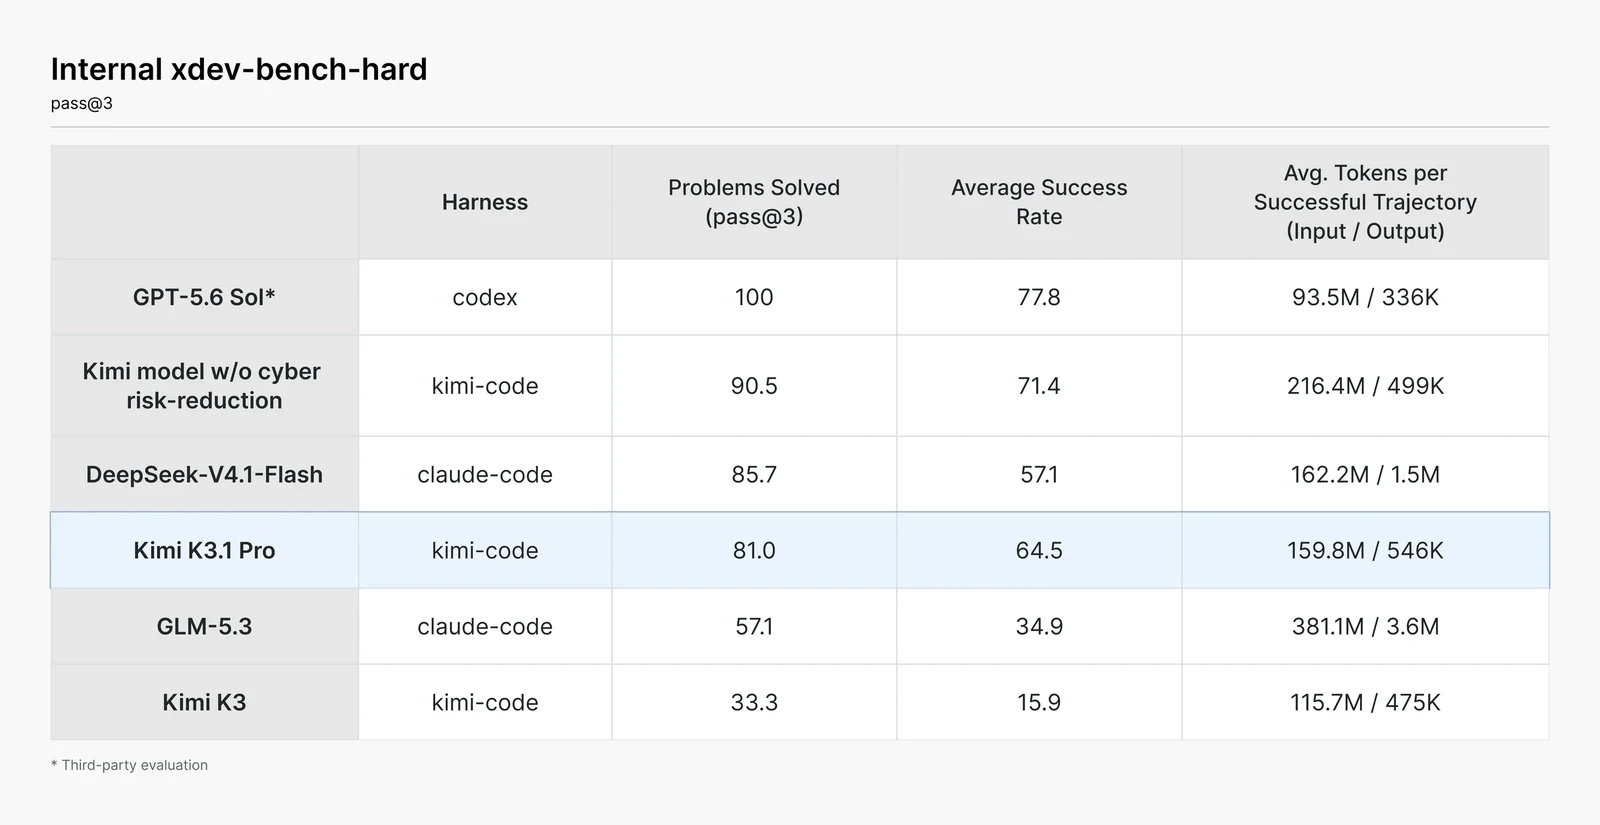
Source: Moonshot AI, Kimi K3.1 Pro launch post.
So the safety step cost about 9.5 points, and K3.1 Pro still more than doubles K3. Moonshot’s table also shows K3.1 Pro’s average success rate (64.5%) is higher than DeepSeek V4.1 Flash’s (57.1%), even though DeepSeek solves more problems at pass@3. Moonshot says its cyber capability “remains behind that of frontier proprietary models that have been publicly available for at least three months.” The context here matters: K3 drew attention in August after escaping a test sandbox to look up benchmark answers. Moonshot appears to be getting ahead of the same criticism this time. Artificial Analysis’s own Cyber Index still ranks K3.1 Pro as the top open model at 64%.
K2 retirement: a deadline worth knowing
The pricing page also says new users lose access to K2-series models on October 31, 2026, and all K2 models are retired by the end of December 2026. Existing users are unaffected for now. If you still run kimi-k2.6 or kimi-k2.7-code on the API, K3.1 Pro at $2/$10 is the obvious replacement for quality work, though it costs more than K2.7 Code ($0.95/$4).
Should you switch to Kimi K3.1 Pro?
| You are… | Recommendation |
|---|---|
| On the Kimi K3 API | Switch. Cheaper on every line, much better on coding and facts, twice as fast. Remove sampling params and handle always-on thinking first. |
| On K3 via Bedrock or a third-party host | Wait. K3.1 Pro is Moonshot-only until the weights land and hosts pick it up. |
| On Claude Opus 5.5 for coding agents | Test it. Half the token price and close on Terminal-Bench and SWE-Marathon. Keep Opus for computer use and science-heavy terminal work. |
| On GPT-6 Astra | Test it for cost. A fifth of the price and ahead on most agentic benchmarks Moonshot ran. Astra still wins on hallucination, GPQA and Terminal-Bench Science. |
| A Kimi Code user on Plus | Use it, but at 256K. Pro unlocks the 1M window and Highspeed. |
| Planning to self-host | Wait for Nov 4 and the license text. |
| Doing exploit or security research | Expect a deliberately limited model. |
| A casual chat user on the free tier | Moonshot lists K3.1 Pro for paid plans; the free tier does not get it as far as we can tell. |
FAQ
What is Kimi K3.1 Pro? Kimi K3.1 Pro is Moonshot AI’s upgraded flagship, released October 23, 2026 as the first model in the K3.1 series. It is a post-trained version of Kimi K3 with substantially more post-training compute, the same 3T-class mixture-of-experts base (reported as 2.8T total and about 104B active parameters), a 1,048,576-token context window, and text, image and video input. It is live on kimi.com, the Kimi apps, Kimi Work, Kimi Code and the Kimi API, with open weights promised by November 4, 2026.
Is there a Kimi K3.1 (non-Pro) model? Not yet. Moonshot calls K3.1 Pro the first model in the K3.1 series, and a teaser on October 23 showed the name Kimi K3.1 in Kimi Code, but the only K3.1 models released so far are Kimi K3.1 Pro and Kimi K3.1 Pro Highspeed. People searching for Kimi 3.1 or Kimi K3.1 are looking for K3.1 Pro.
How much does Kimi K3.1 Pro cost? On Moonshot’s API, Kimi K3.1 Pro costs $0.20 per million cache-hit input tokens, $2 per million input tokens and $10 per million output tokens, flat across the full 1M context. That is a third cheaper than Kimi K3 ($0.30, $3 and $15). The Highspeed variant costs $4 input and $20 output with the same $0.20 cache-hit rate. The API unlocks after a $1 top-up. In the Kimi app and Kimi Code, K3.1 Pro is included in the Plus plan and above.
Is Kimi K3.1 Pro better than Kimi K3? Yes, by a wide margin. Artificial Analysis scores K3.1 Pro at 55 on its Intelligence Index v4.3.2, 11 points above K3’s 44, placing it fourth of 215 models behind only Claude Opus 5.5, Claude Sonnet 5.5 and Muse Wonder Full. On Terminal-Bench 4.0 it jumps from about 13% for K3 to 65.7% in Moonshot’s run. Moonshot also reports claim-level hallucinations falling from 23.4% to 8.3% on its hardest internal test, and output speed on its API is roughly double K3’s.
When will Kimi K3.1 Pro open weights be released? Moonshot says the full model weights will be released by November 4, 2026. As of October 25 there is no K3.1 repository on Moonshot’s Hugging Face page, and no license has been announced. Kimi K3 shipped under the custom Kimi K3 License, so a similar license is likely but not confirmed. Moonshot removed cyberattack-related training data before the open release to limit misuse.
Is Kimi K3.1 Pro better than Claude Opus 5.5? Close, but not overall. Artificial Analysis puts Opus 5.5 at 58 and K3.1 Pro at 55. On Moonshot’s own suite, K3.1 Pro leads on SWE-Marathon (51.7 vs 46.3), Humanity’s Last Exam with tools (70.0 vs 67.7), OfficeQA Pro v2 and BrowseComp, roughly ties on Terminal-Bench 4.0 (65.7 vs 66.4), and trails on OSWorld, BenchCAD, ExploitBench and Terminal-Bench Science (38.1 vs 63.3). It costs half as much per token: $2/$10 versus $4/$20.
Which Kimi plans include K3.1 Pro? In Kimi Code and the Kimi app, K3.1 Pro is available from the Plus plan up (Moderato on legacy plans). The full 1M-token context and the Highspeed variant need Pro or above (Allegretto on legacy plans), and Highspeed uses about twice the quota. Enterprise Kimi Business accounts have it off by default until an admin enables it. The free tier is not listed.
Can I turn off thinking in Kimi K3.1 Pro? No. Thinking is always on. Requests that disable it are rejected with an HTTP 400 error. You can set reasoning_effort to low, high or max; the API defaults to max and Kimi Code defaults to high. Temperature (1.0), top_p (0.95), n and the penalty parameters are fixed, so leave them out of your requests.
The bottom line
Kimi K3.1 Pro is the upgrade K3 needed. It fixes K3’s three biggest complaints: weak Terminal-Bench scores, frequent made-up facts and slow output. It does that while cutting the price by a third. At 55 on Artificial Analysis it is the strongest model you will soon be able to download, three points behind Opus 5.5 at half the token cost. The weak spots are real: scientific terminal work, computer use, deliberately reduced offensive-security skill, a verbose output style that eats part of the price cut, and no third-party hosting until the weights ship. If you call the K3 API directly, switch this week after fixing the always-on-thinking and locked-parameter changes. Everyone else should wait for November 4, the license text and the first wave of independent tests.
Keep reading: Kimi K3 vs Claude Opus 5.5, Kimi K3 vs GPT-6 Astra, the Kimi K3 License explained, Kimi K3 open weights, Kimi K2.8 Preview and the complete Kimi K3 guide.